Artificial intelligence is rapidly becoming embedded in everyday enterprise workflows. Microsoft Copilot is one of the most visible examples of this shift, bringing generative AI directly into tools like Word, Excel, Teams, and PowerPoint. For many organizations, Copilot promises faster decisions, automated insights, and significant productivity gains.
But there is a critical reality that many companies are only beginning to understand.
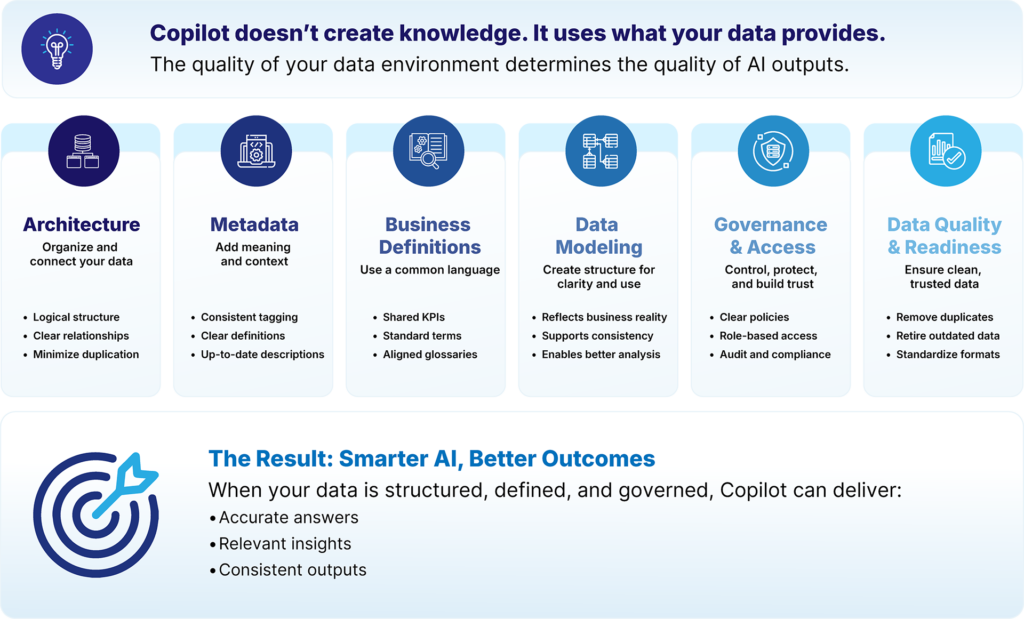
Copilot does not create knowledge. It reflects the data environment it is given.
If that environment is inconsistent, poorly structured, or lacking clear definitions, Copilot will not correct those issues. It will amplify them.
This raises an important question for any organization adopting Copilot:
What must be in place to ensure Copilot is working with accurate, consistent, and trusted data?
The answer is not a single tool or configuration. It is a combination of data architecture, metadata management, governance, and modeling practices working together.
This article explores the steps organizations need to take to prepare their data environment for Copilot, and why these foundational elements determine whether AI delivers value or introduces risk.
“Every company has messy data, and even the best of AI companies are not fully satisfied with their data.”
- Andrew Ng, Founder of DeepLearning.AI
To understand what Copilot needs, it is important to understand how it works.
When a user enters a prompt, Copilot retrieves information from across Microsoft 365 using Microsoft Graph. This includes content from SharePoint, OneDrive, Teams, Outlook, and other enterprise systems.
Copilot does not operate on a curated dataset. It operates on whatever data the user has access to.
This means three things:
If your data environment resembles a “digital junk drawer,” Copilot will reflect that back in its outputs.
This is why preparing your data for Copilot is not optional. It is foundational.
Data architecture is the backbone of any Copilot deployment.
Without a well-defined structure, data becomes fragmented across systems, duplicated in multiple locations, and difficult to interpret. Copilot will still access that data, but the results will lack consistency and reliability.
A strong data architecture ensures that:
When architecture is inconsistent, Copilot encounters multiple versions of the same concept. For example, revenue might be defined differently across systems, or customer data may be duplicated across platforms.
Copilot cannot resolve these inconsistencies. It can only surface them.
Organizations preparing for Copilot should begin by assessing:
This step is not about optimizing for AI. It is about ensuring that the foundation AI depends on is coherent.
Copilot relies heavily on metadata to interpret content.
Metadata describes what data represents, how it should be used, and how it relates to other data. Without it, Copilot can retrieve information, but it cannot fully understand its meaning.
Rich, consistent metadata allows Copilot to:
In environments like SharePoint, metadata is critical because it helps Copilot understand the purpose and relationships of documents and datasets.
When metadata is inconsistent or missing, Copilot may:
To prepare metadata for Copilot, organizations should focus on:
Metadata is not just descriptive. It is interpretive. It tells Copilot how to think about your data.
One of the most overlooked challenges in Copilot deployments is inconsistent business definitions.
Different teams often define the same metric in different ways. These inconsistencies may not be visible in individual reports, but they become highly visible when Copilot aggregates and interprets data across systems.
Without standardized definitions:
Copilot does not choose a correct definition. It reflects the underlying inconsistency.
Standardization requires aligning:
When these elements are consistent, Copilot can generate outputs that align with how the business actually operates.
When they are not, Copilot introduces confusion at scale.
Data models play a critical role in ensuring Copilot outputs are accurate.
They define how data is structured, how entities relate to each other, and how systems interpret information. Without strong modeling practices, data becomes difficult to manage and even harder for AI to interpret consistently.
Organizations should ensure that data models are:
This is where integration becomes essential.
Tools like Microsoft Purview provide governance capabilities, including classification, labeling, and compliance controls. However, these tools depend on accurate and up-to-date metadata.
If data models are not connected to governance systems:
Connecting modeling tools with governance platforms ensures that:
This alignment is what transforms governance from documentation into enforcement.
Copilot operates within the permissions already defined in Microsoft 365.
If a user has access to a file, Copilot can access it. If permissions are overly broad, Copilot may surface sensitive or irrelevant information.
This creates a significant risk.
Research has shown that organizations often have large volumes of overexposed or poorly governed data, increasing the likelihood of unintended access.
To mitigate this risk, organizations should:
Copilot does not override your access controls. It inherits them.
This means governance failures become AI failures.
AI systems are highly sensitive to data quality.
Duplicate, outdated, or inconsistent data reduces the reliability of Copilot outputs. In many organizations, data sprawl is a significant issue, with large volumes of redundant and inactive data stored across systems.
Improving data quality involves:
Data minimization is also important. Reducing unnecessary data not only improves quality but also reduces risk.
When Copilot interacts with cleaner, more reliable data, its outputs become more consistent and trustworthy.
データガバナンス is essential for Copilot success.
Without governance, organizations risk exposing sensitive information, violating compliance requirements, and producing unreliable outputs.
Effective governance ensures:
Governance also ensures that data remains accurate and relevant over time, which is critical for AI systems that rely on current information.
As AI adoption increases, governance must evolve from static policies to dynamic systems that can scale with data complexity.
Many organizations treat AI as a layer added on top of existing systems.
This approach often leads to poor results.
Instead, organizations should design their data environment with AI in mind.
This includes:
AI is inherently data-centric. Its performance depends on the quality, structure, and clarity of the data it consumes.
Organizations that treat data preparation as an afterthought will struggle to realize the full value of Copilot.
Copilot introduces a new level of visibility into your data environment.
It surfaces connections, relationships, and inconsistencies that may have previously gone unnoticed.
This creates both opportunity and risk.
On one hand, organizations can unlock faster insights and improved productivity.
On the other, they risk exposing inconsistencies, inaccuracies, and governance gaps at scale.
The difference comes down to preparation.
“The intelligence layer of any AI system is only as good as the context you give it.”
- Satya Nadella, Microsoft CEO
Preparing data for Copilot requires more than governance tools alone.
It requires a clear understanding of how data is structured, defined, and connected across systems.
This is where data modeling plays a central role.
ER/Studio helps organizations:
By grounding governance and metadata in data models, organizations can ensure that Copilot is working with data that is both accurate and consistent.
This is not just about improving AI outputs. It is about creating a data environment that can scale with AI adoption.
Microsoft Copilot represents a significant step forward in how organizations interact with data.
But its effectiveness is determined long before a user enters a prompt.
It is determined by how data is structured, defined, governed, and maintained.
Organizations that invest in:
will see Copilot deliver meaningful value.
Those that do not will see AI reflect and amplify existing issues.
The path forward is clear.
Start with your data.
See how ER/Studio helps you build the data foundation Copilot depends on. Request a demo today.
Microsoft Copilot retrieves data based on user permissions and relevance signals from Microsoft Graph. It pulls from sources like SharePoint, Teams, and OneDrive, prioritizing content the user has access to and that appears contextually related to the prompt.
This means Copilot is not selecting from a curated dataset. It is selecting from everything available within that user’s access scope. If important data is poorly organized, inconsistently labeled, or buried in unstructured locations, Copilot may prioritize less relevant or lower-quality sources instead.
Improving how data is organized and labeled directly improves what Copilot chooses to surface.
The most common issues are not missing data, but conflicting or ambiguous data.
For example, Copilot struggles when:
– The same metric is defined differently across reports
– Documents use inconsistent terminology for the same concept
– Multiple versions of datasets exist without clear ownership
In these cases, Copilot may return answers that appear complete but are internally inconsistent. These problems are often invisible in isolated systems but become obvious when AI aggregates across them.
The key issue is not volume of data, but lack of alignment.
Business glossaries and data dictionaries provide structured meaning that Copilot can rely on when interpreting data.
A glossary defines what a term means in a business context, while a data dictionary defines how that term is represented in systems. When these are aligned, Copilot can more accurately connect language in prompts to actual data structures.
Without this alignment, Copilot may treat similar terms as unrelated or assume relationships that do not exist. This leads to answers that sound correct but are based on incorrect assumptions.
Well-maintained glossaries and dictionaries reduce ambiguity and improve how Copilot interprets both structured and unstructured content.
Microsoft Purview provides visibility into data assets, classifications, and governance policies, but it relies on accurate metadata to function effectively.
When data models are integrated with Purview:
– Metadata reflects actual system structures
– Definitions remain consistent across tools
– Changes in data architecture are captured and propagated
This improves Copilot’s ability to retrieve relevant and governed data because the underlying metadata is more reliable.
Without integration, governance tools can become disconnected from how data is actually implemented, reducing their effectiveness and increasing the risk of inconsistent AI outputs.
ER/Studio helps organizations define and maintain the structure and meaning of their data before it is consumed by tools like Copilot.
It enables teams to:
– Create and standardize logical and physical data models
– Align technical structures with business definitions
– Maintain consistent data dictionaries across systems
By doing this, ER/Studio ensures that the data Copilot accesses is not just available, but clearly defined and consistently structured.
This reduces ambiguity, improves metadata quality, and creates a more reliable foundation for AI-driven outputs.