
Modern data teams rarely work within a single database platform anymore. Enterprise environments now span multiple relational systems, cloud warehouses, analytics engines, and application databases. A single organization might operate SQL Server transactional systems, Snowflake analytics warehouses, MongoDB application databases, BigQuery machine learning pipelines, and Databricks lakehouse environments simultaneously.
Each platform solves a different problem. SQL Server provides dependable transactional processing. Snowflake enables scalable analytics across cloud infrastructure. MongoDB supports flexible application data models. BigQuery delivers high performance analytics across massive datasets. Databricks brings together machine learning, data engineering, and large scale analytics.
The challenge appears when organizations attempt to manage all of these platforms as part of a single architecture. Data definitions diverge. Governance policies drift. Documentation becomes outdated. Engineers begin to lose visibility into how data moves across the organization.
This is why modern data modeling has evolved beyond individual databases. Today it must connect relational systems, cloud warehouses, document databases, governance platforms, and DevOps pipelines into a unified data architecture.
Platforms like ER/Studio were designed to address this challenge by supporting data modeling across the full data ecosystem while integrating with the tools organizations already use.
To understand why this matters, it helps to examine how modern enterprises actually manage their data environments.
Most enterprises now operate in what architects call a polyglot data environment. Instead of standardizing on a single database technology, organizations deploy different systems depending on workload requirements.
Transactional systems often rely on relational databases such as Microsoft SQL Server, Oracle, PostgreSQL, or MySQL. These platforms excel at maintaining consistency for operational data such as financial records, customer transactions, and order processing.
Analytics teams frequently use Snowflake, Google BigQuery, Amazon Redshift, or Databricks to process large volumes of data and support business intelligence. These platforms are optimized for analytical queries and large scale reporting.
Meanwhile, application development teams increasingly rely on MongoDB and other document databases that store flexible JSON structures and allow developers to iterate quickly as applications evolve.
Each of these technologies is valuable. However, when they operate independently, organizations begin to lose a coherent view of their overall data architecture.
Over time this fragmentation introduces several problems.
Teams may use different definitions for the same data elements. Analysts may not know where a dataset originated. Engineers may deploy schema changes without understanding downstream dependencies. Governance teams may struggle to enforce policies across systems that were never designed to work together.
This is where enterprise data modeling becomes critical.
Snowflake has rapidly become one of the most widely adopted cloud data platforms for analytics and data warehousing. Organizations use Snowflake to process massive volumes of structured and semi structured data while benefiting from elastic compute scaling.
However, Snowflake environments often grow quickly. As more teams begin ingesting data, the number of schemas, tables, and transformations can increase dramatically. Without careful design, warehouse structures become difficult to navigate and maintain.
Snowflake data modeling helps organizations maintain structure and governance within these rapidly expanding environments. Data models define how datasets relate to one another, establish naming standards, and document how analytics layers are built from operational systems.
ER/Studio enables teams to design and document Snowflake warehouse schemas while maintaining alignment with logical enterprise models. This allows analytics teams to scale Snowflake environments without sacrificing architectural clarity.
While cloud warehouses attract significant attention, relational databases such as Microsoft SQL Server remain essential components of enterprise infrastructure. SQL Server continues to power mission critical systems across industries including finance, healthcare, retail, and manufacturing.
These operational systems often contain the most important data in the organization. Maintaining a clear architectural understanding of SQL Server schemas is essential for reliability and governance.
SQL Server data modeling allows architects and developers to design relational schemas that support application requirements while maintaining consistency across systems. Modeling also helps teams understand how transactional data flows into downstream analytics platforms.
ER/Studio supports SQL Server data modeling by allowing teams to reverse engineer existing databases, maintain logical models that reflect business concepts, and ensure that physical implementations align with enterprise architecture standards.
Application developers frequently choose MongoDB because of its flexibility. Instead of requiring rigid relational schemas, MongoDB stores data as JSON-like documents that can evolve alongside application features.
This flexibility accelerates development but introduces new architectural challenges.
As applications evolve, document structures may diverge across collections. Fields may appear in some records but not others. Without documentation, it becomes difficult for teams to understand how application data is structured.
MongoDB schema design benefits from modeling just as relational systems do. Document models can be represented within enterprise data models, allowing architects to capture relationships, document structures, and maintain alignment with broader data architecture standards.
ER/Studio supports modeling of JSON and document based data structures so organizations can maintain visibility into application data while still allowing developers the flexibility they need.
Google BigQuery has become a leading platform for large scale analytics and machine learning workloads. Its serverless architecture allows organizations to analyze enormous datasets without managing infrastructure.
However, BigQuery environments often ingest data from numerous sources including operational databases, streaming pipelines, SaaS platforms, and external partners.
Designing an effective BigQuery data architecture requires careful planning. Data models help define how raw data is transformed into curated datasets that support reporting and analytics.
By modeling BigQuery structures alongside other enterprise systems, organizations can maintain clear lineage from operational sources to analytical outputs. ER/Studio helps teams document these relationships and maintain architectural consistency across the data lifecycle.
The rise of the Databricks lakehouse architecture has introduced a new approach to managing large scale data platforms. Databricks combines the flexibility of data lakes with the structure and performance of data warehouses.
This model allows organizations to support analytics, machine learning, and data engineering workloads within a single platform.
However, lakehouse environments often integrate data from numerous upstream systems. Maintaining visibility into these relationships becomes essential for governance and reliability.
Databricks modeling allows organizations to document datasets, transformation layers, and analytical structures within lakehouse environments. When integrated with broader enterprise models, these structures become part of a unified architecture that spans operational databases and analytics platforms.
Modern data architecture extends far beyond database design. Governance platforms, development pipelines, and security systems all play critical roles in managing enterprise data environments.
Organizations often rely on governance tools such as Collibra and Microsoft Purview to maintain business definitions, stewardship policies, and data catalogs. These systems depend on accurate metadata from underlying databases and analytics platforms.
Data modeling platforms help bridge this gap by synchronizing technical metadata with governance catalogs.
Similarly, DevOps platforms such as GitHub, GitLab, Bitbucket, and Azure Repos allow teams to manage schema changes through version control and automated deployment pipelines. When modeling tools integrate with these systems, database architecture becomes part of the same lifecycle as application code.
Identity providers such as Okta and Microsoft Entra ID add another layer by controlling access to modeling environments and ensuring that only authorized users can modify architectural assets.
Together, these integrations create an ecosystem where data architecture, governance, development, and security operate as a unified system.
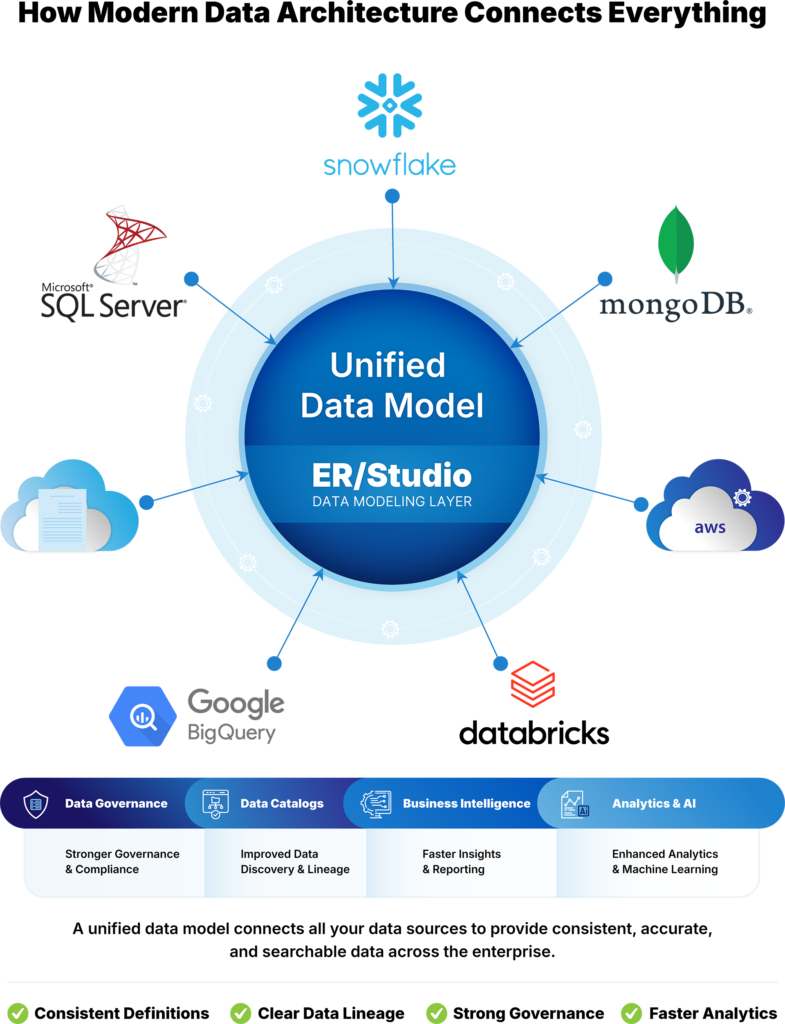
ER/Studio serves as the architectural layer that connects these diverse technologies.
Instead of modeling each platform independently, ER/Studio allows teams to create logical models that represent business concepts and relationships. These logical models can then be mapped to physical implementations across relational databases, cloud warehouses, document databases, and analytics platforms.
Because ER/Studio integrates with technologies such as Snowflake, SQL Server, MongoDB, BigQuery, Databricks, GitHub, Jira, Collibra, Purview, Okta, and many others, it allows organizations to maintain a unified understanding of their data environment.
This unified perspective helps teams manage complexity while maintaining governance, security, and collaboration across the enterprise.
As enterprise data ecosystems continue to grow, the ability to maintain a clear architectural view becomes increasingly important. Organizations must manage relational systems, analytics platforms, application databases, and machine learning environments simultaneously.
The most successful data teams approach this challenge by creating a unified architecture that spans every platform.
By integrating with leading technologies across databases, governance systems, DevOps pipelines, and security platforms, ER/Studio helps organizations maintain clarity, consistency, and control across modern data environments.
For enterprises navigating the complexity of Snowflake, SQL Server, MongoDB, BigQuery, Databricks, and other platforms, that unified perspective can make all the difference.
See how ER/Studio can unify your data architecture across every platform and eliminate fragmentation at scale.
Snowflake data modeling is the process of designing warehouse schemas and relationships within the Snowflake cloud data platform. It helps organizations structure analytics environments, document dataset relationships, and maintain consistent governance across warehouse tables.
SQL Server data modeling helps organizations design relational schemas that support transactional systems while maintaining alignment with enterprise architecture. Modeling also helps teams understand how operational data flows into analytics platforms and downstream applications.
MongoDB schema design refers to defining how document based data structures are organized within MongoDB collections. Although MongoDB allows flexible JSON structures, schema design helps maintain consistency and documentation across application databases.
BigQuery data architecture defines how datasets, tables, and transformation layers are organized within Google BigQuery environments. Proper architecture ensures efficient querying, clear lineage, and maintainable analytics pipelines.
Databricks modeling involves designing datasets and transformation layers within the Databricks lakehouse platform. It helps organizations manage data engineering workflows, analytics models, and machine learning datasets within a governed architecture.
Yes. Modern data modeling platforms such as ER/Studio are designed to support relational databases, document stores, and cloud data warehouses simultaneously. This allows organizations to maintain a consistent architecture across complex environments.


